Built with Claude Code. All data is synthetic, except one photo of a handwritten order found online. It has no names on it, and the sender is fictional.
The question
Most of the work in an ordering process isn’t hard thinking. It’s the same small decision made over and over: which product does this line mean, and does the quantity make sense?
General LLMs can make that decision, but every call means reading a long prompt and reasoning in text. That’s slow and expensive at volume, and a “high / medium / low” confidence label is hard to set a threshold on.
A System 1 model works differently. It’s built for quick, single decisions. You give it the options, and it returns a choice with a calibrated probability. I wanted to know whether splitting the work holds up on a messy real-world process: a general model does the reading, and a System 1 model makes the decisions.
The process I tested
Contractors order by text message: “15 of the 2x4 not treated, hurricane ties 50, mud x3.” A rep reads it, finds every product in a 200-item catalog, and checks the quantities. Most lines are routine. A few need a person.
The goal isn’t to automate the order. It’s to tell the rep which lines they can safely skip.
The setup
Claude + Jev:
- Claude reads the message and pulls out each line: quantity, unit, what was asked for.
- Fuzzy search shortlists 20 candidate products per line.
- Jev, TypeSafe’s System 1 model, picks the product from that shortlist and gives a probability. A second question checks that the quantity makes sense for that product.
- One threshold decides what the rep sees. Lines above it are pre-approved. Lines below it are flagged, with the reason and the top three alternatives.
Claude only: the same Claude reading step, then one Claude call that matches every line against the full catalog and rates its confidence high, medium or low.
To keep the comparison fair:
- Both pipelines share the reading step, and get the same business rules (house defaults such as “2x4 means SPF #2 kiln-dried”).
- The cost comparison covers only the matching step, where the two pipelines differ.
- Neither pipeline can see the answer key. A test fails if application code reads it.
- A blind labeler re-labeled the answer key without seeing mine. It caught an assumption I’d baked in: “15 of the 2x4” had quietly been labeled as 8-foot.
- An auditor recomputed every metric from the raw files. It caught timing numbers that came from different runs.
How it got there
1. Jev lost the first run
Claude alone pre-approved 65 lines. Jev pre-approved 38. The easy move was to tune until Jev won. I looked for the cause instead.
2. Two of the bugs were mine
Search for “not treated” returned only treated lumber, so the right product never reached Jev’s shortlist. The option text left out trade nicknames, like “mud” for drywall compound. A System 1 model can only choose from the options it’s given, so the quality of those options matters as much as the model does.
3. I was asking the wrong question at the wrong time
I asked “is this quantity sensible?” before Jev knew which product the line was. Without a product, “50” has no unit, so Jev flagged most lines that didn’t state one. Asking after the product is chosen, with its selling unit named, raised Jev’s auto-approvals from about 49% to about 73%. A check confirmed the gate still caught real errors: “100 feet of tape”, for a product sold by the roll, scored 0.18.
This was the most useful finding in the project. A System 1 model answers exactly the question it’s asked, so it pays to break a decision into steps in the right order.
4. A re-run made the accuracy result level
After I reworded one prompt heading, Claude-only accuracy went from 100% to 98.9%. Both pipelines now miss exactly one line, and both flag it. One run of 88 lines can swing a line either way, so I report accuracy as level, not as a win for either side.
Results
20 synthetic text orders, 88 lines:
| Claude only | Claude + Jev | |
|---|---|---|
| Right product | 87 of 88 | 87 of 88 |
| Pre-approved | 66 of 88 | 66 of 88 |
| Wrong among pre-approved | 0 | 0 |
| Matching time per order | about 2.5 s | about 0.5 s |
| Matching cost per order | about $0.037 | about $0.001 |
| Total cost per 10,000 orders | about $456 | about $101 |
- Same decisions, much cheaper. Jev’s matching step is about 36× cheaper and about 4.7× faster on the clock, because each line is its own small call and they run in parallel. Added up across every call, it’s about 1.3× faster. The whole order costs about 4.5× less.
- The confidence is usable. Jev’s probabilities were well calibrated. Every line it was at least 70% sure of was right, so a single threshold does the routing. I save the raw scores, so moving the threshold re-routes lines instantly, with no new API calls.
- The reading step is now the main cost. In the Claude + Jev pipeline, about nine-tenths of the cost per order is Claude reading the message. Any further savings have to come from the reading step.
- Three of four lines need no review. The rep’s attention goes to the one in four that does.
The caveats: 20 orders, tuned on the same orders, and costs estimated from token counts at list prices. This shows Jev is cheaper at the same quality, not that it is more accurate. Prompt caching on the Claude-only catalog prompt would narrow the gap, and I haven’t tested it yet.
What the rep sees
Calibrated confidence only pays off if the screen turns it into attention. My first screen didn’t.
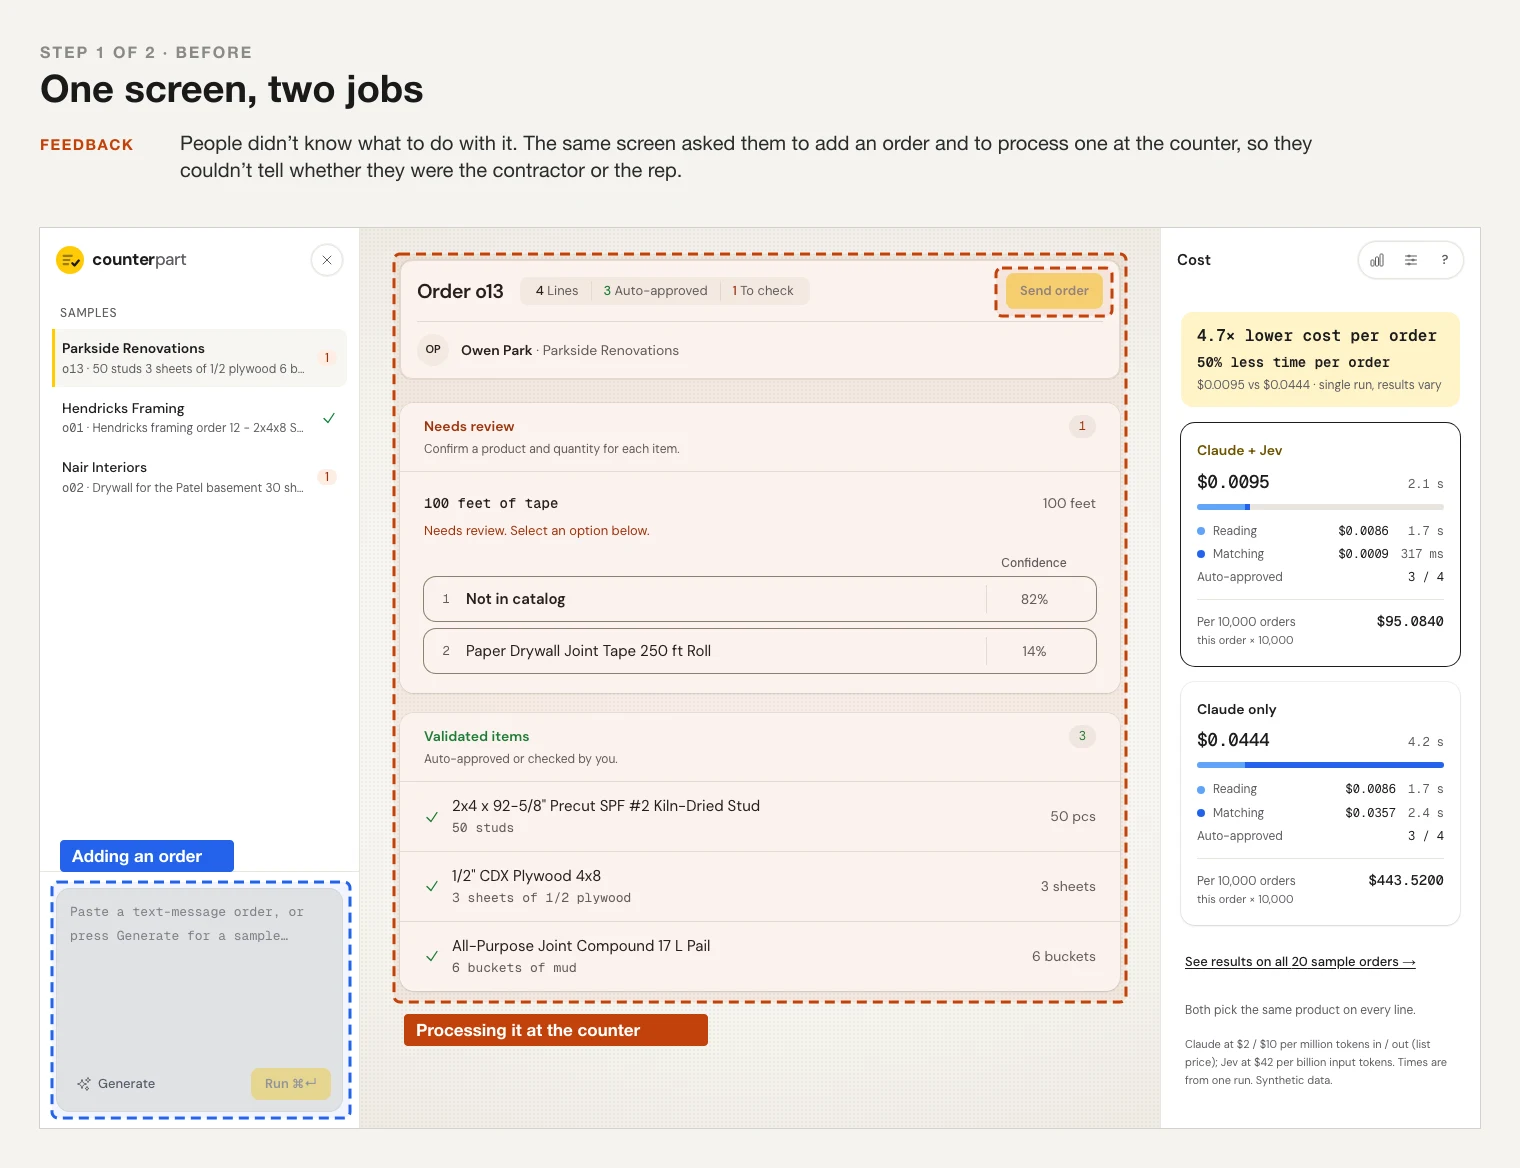
People didn’t know what to do with it. The same screen asked them to add an order (a paste box, Generate and Run) and to process one at the counter (review the lines, Send order). They couldn’t tell whether they were the contractor or the rep.
So I took adding orders off the screen and gave it one job: processing orders. Orders arrive in a queue, and the rep moves each one from Received to Sent to Approved. They check the flagged lines and create the quote, and the contractor approves it before it goes to the ERP. Then I sharpened the design for triage, so the eye lands on what’s uncertain and everything else recedes.
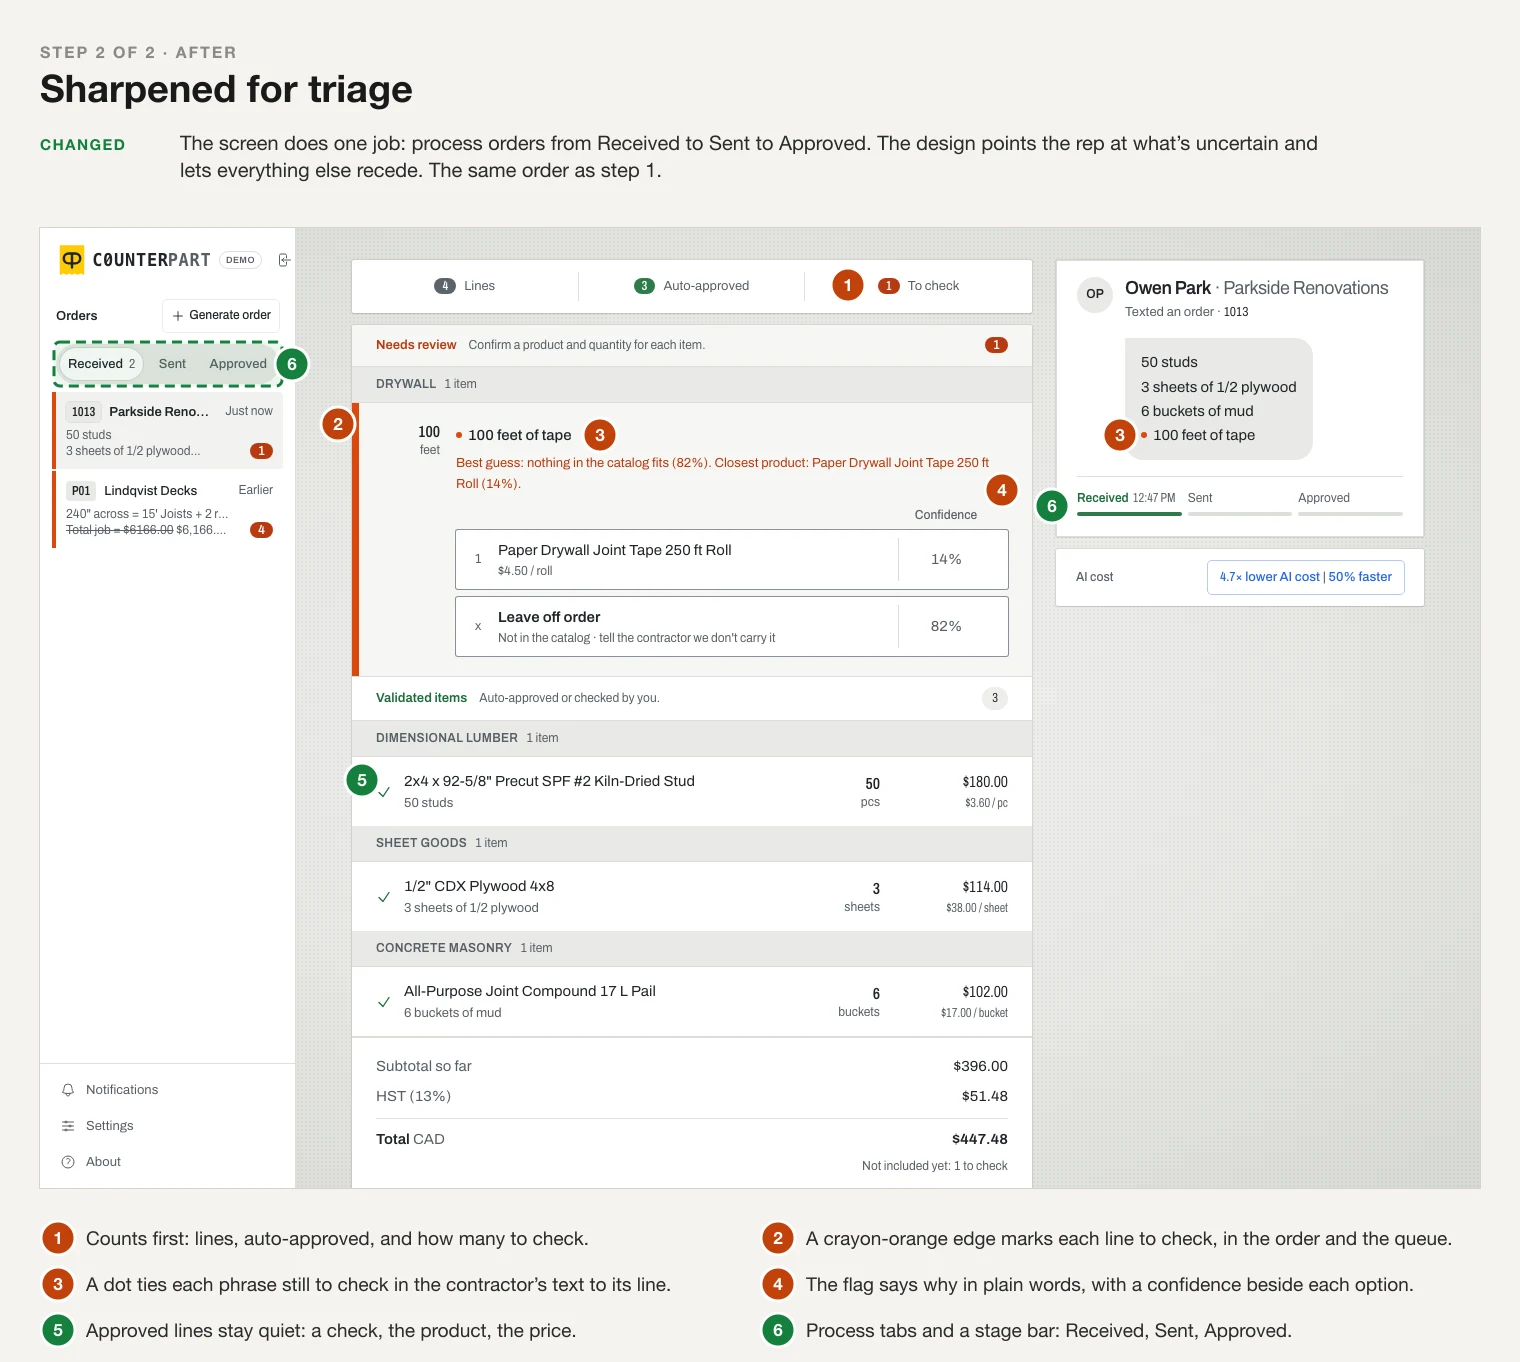
- Counts first: lines, auto-approved, and how many to check.
- A crayon-orange edge marks each line to check, in the order and in the queue.
- A dot ties each phrase still to check in the contractor’s text to its line.
- The flag says why in plain words, with the model’s confidence beside each option.
- Approved lines stay quiet: a check, the product, the price.
- Process tabs and a stage bar show where each order is: Received, Sent or Approved.
The model decides which lines are uncertain. The screen makes sure the rep spends their time on those lines and no others.
Harder inputs
A photo of a handwritten order
Plenty of orders arrive as a photo of a working page: a sketch, prices, labour, crossed-out totals, and the lumber list somewhere in the middle. I added one, a real deck estimate found online. Claude transcribes the photo word for word, marks crossed-out text, and the transcription goes through both pipelines unchanged.
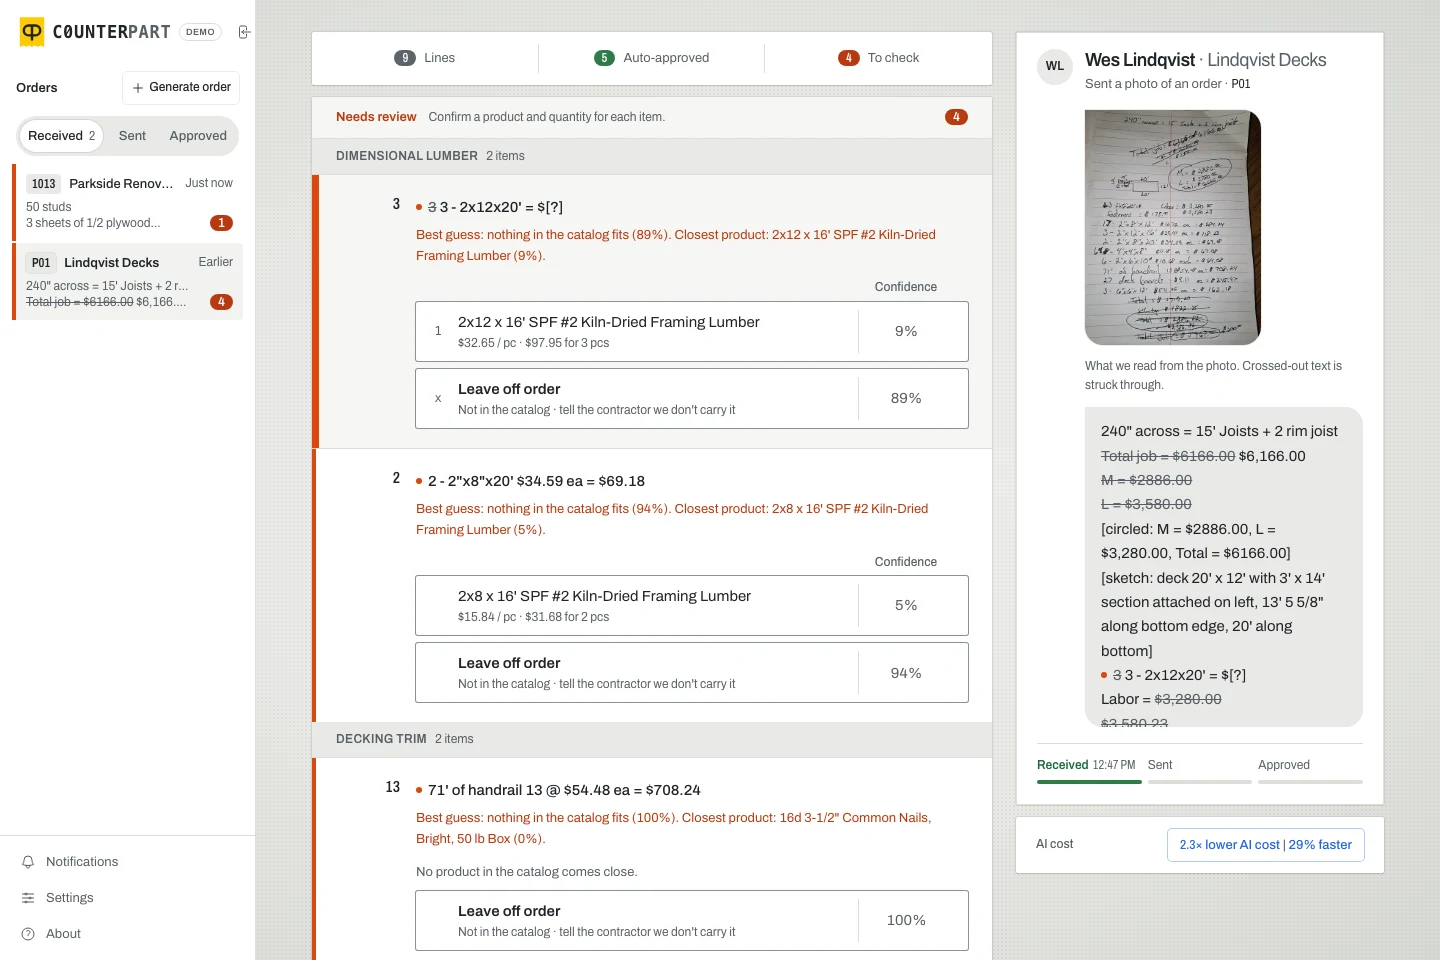
- Transcribing took 2–5 seconds and cost under a cent. It caught an “8” written over a “6” and kept the 6. It misread “17” as “1?” on one run of two.
- Prices, totals, labour and a lump sum for fasteners didn’t become order lines.
- The stock lumber matched with high confidence. The 20-foot boards, the handrail and the unsized “deck boards” came back with no match. The catalog doesn’t carry them, so that’s the right answer, and a rep needs to ask about them anyway.
Reading a photo is a cost both pipelines share, so it narrows the gap. On this order, the saving drops from 2.7× to 2.3×. The photo order isn’t in the results table yet, because it needs labeling from the photo first.
Rules that sit beside the confidence
Some lines need a rep for reasons a model’s confidence can’t capture. Metric sizes are one example. “150 x 50” is rewritten to 2x6 and “4.8m” to 16’ before matching, and every converted line goes to the rep, even when Jev is sure of the product. Routing combines the model’s probability with business rules. The model doesn’t have to carry everything.
What this suggests
The pattern carries over to any process built on many small, repeated decisions over a known set of options, such as matching, classifying or checking:
- Use a general model where the input is open-ended: reading a message, a photo, a document.
- Hand each repeated decision to a System 1 model, with a short list of good options and a clear question.
- Route on its probability, add business rules where judgment is required, and send everything else to a person.
On this process, that cut the decision step’s cost by about 36× without losing accuracy.
What’s next
So far, the matching has run against a clean catalog: tidy names, nicknames, one selling unit per product. A real yard’s item master is messier. It has terse descriptions and unit codes, lumber priced per thousand board feet, deck boards priced by the foot but sold by the piece, and item codes replaced by newer ones. I’ve built one for a second fictional yard. The next test is whether the split still holds when the catalog is as messy as the orders.
The hard part isn’t reading the order. It’s deciding what the rep doesn’t need to check, and doing it cheaply enough to run on every line.
Not affiliated with any company.